On this page
Identify the real header row
A report title or unit label above a table can be mistaken for a header. Keep the row that defines the columns and remove unrelated lines.
When a table uses multi-level headers, preserve the information explicitly or finish the structure in a spreadsheet application.
Remove empty and decorative rows
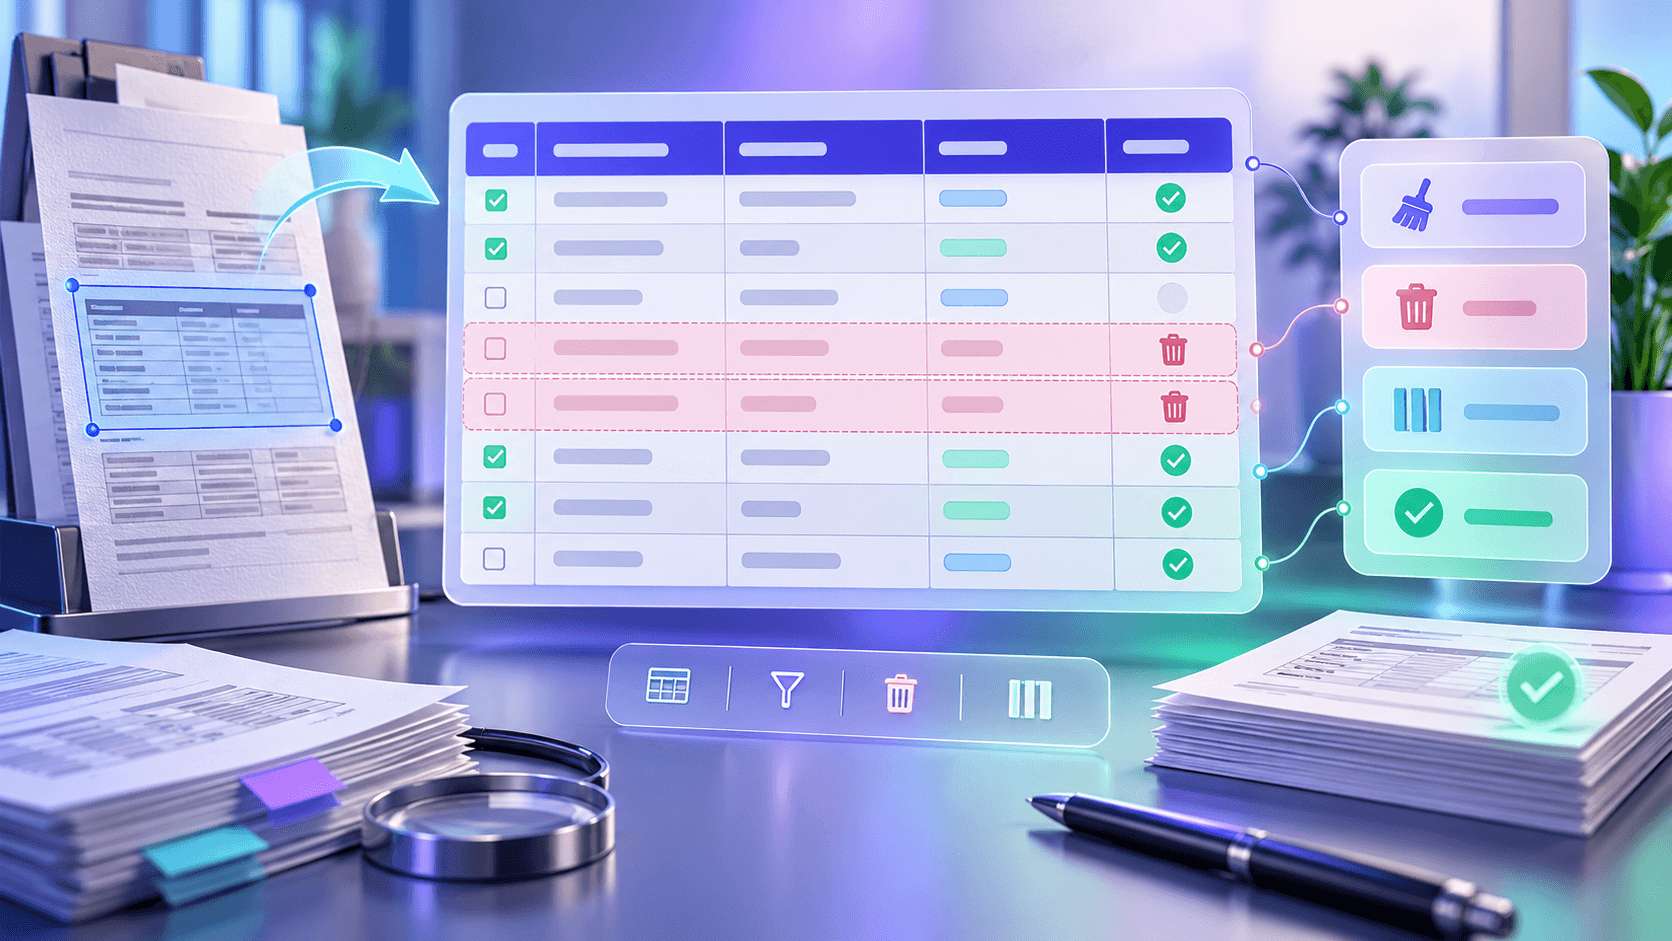
Whitespace, separator rules and wrapped captions can create sparse rows. Remove rows that do not carry data, but keep intentional blank values inside meaningful records.
Do not treat a missing value as zero unless the source explicitly says so.
Correct grouping and cell text
Compare dates, decimals, currency symbols, parentheses and minus signs with the highlighted source. These characters can materially change meaning.
If two source columns were combined, add a column and move values deliberately rather than guessing.
Preserve an auditable source reference
Use descriptive table names that include page context. Keep the original PDF alongside the spreadsheet so another reviewer can reproduce the extraction decision.
Put the workflow into practice
Choose a searchable PDF, tune the page scope, compare detected regions with editable grids, then export and verify only the reviewed tables.
Try Extract Tables from PDFFrequently asked questions
Clear answers before you extract tables
Can I edit cells before export?
Yes. The review grid supports direct cell corrections.
Can I remove unwanted rows and columns?
Yes. Remove decorative or incorrectly grouped rows and columns before export.
Should empty cells be deleted?
Not automatically. An empty cell may be meaningful within a record.
Does cleanup modify the source PDF?
No. It only changes the extracted data model.