On this page
Use CSV for simple portable data
CSV is plain text and works well for one flat table. It is easy to import into databases, scripts and spreadsheet software.
Choose the delimiter expected by the receiving system. Commas, semicolons and tabs behave differently across locales.
Use XLSX for multiple reviewed tables
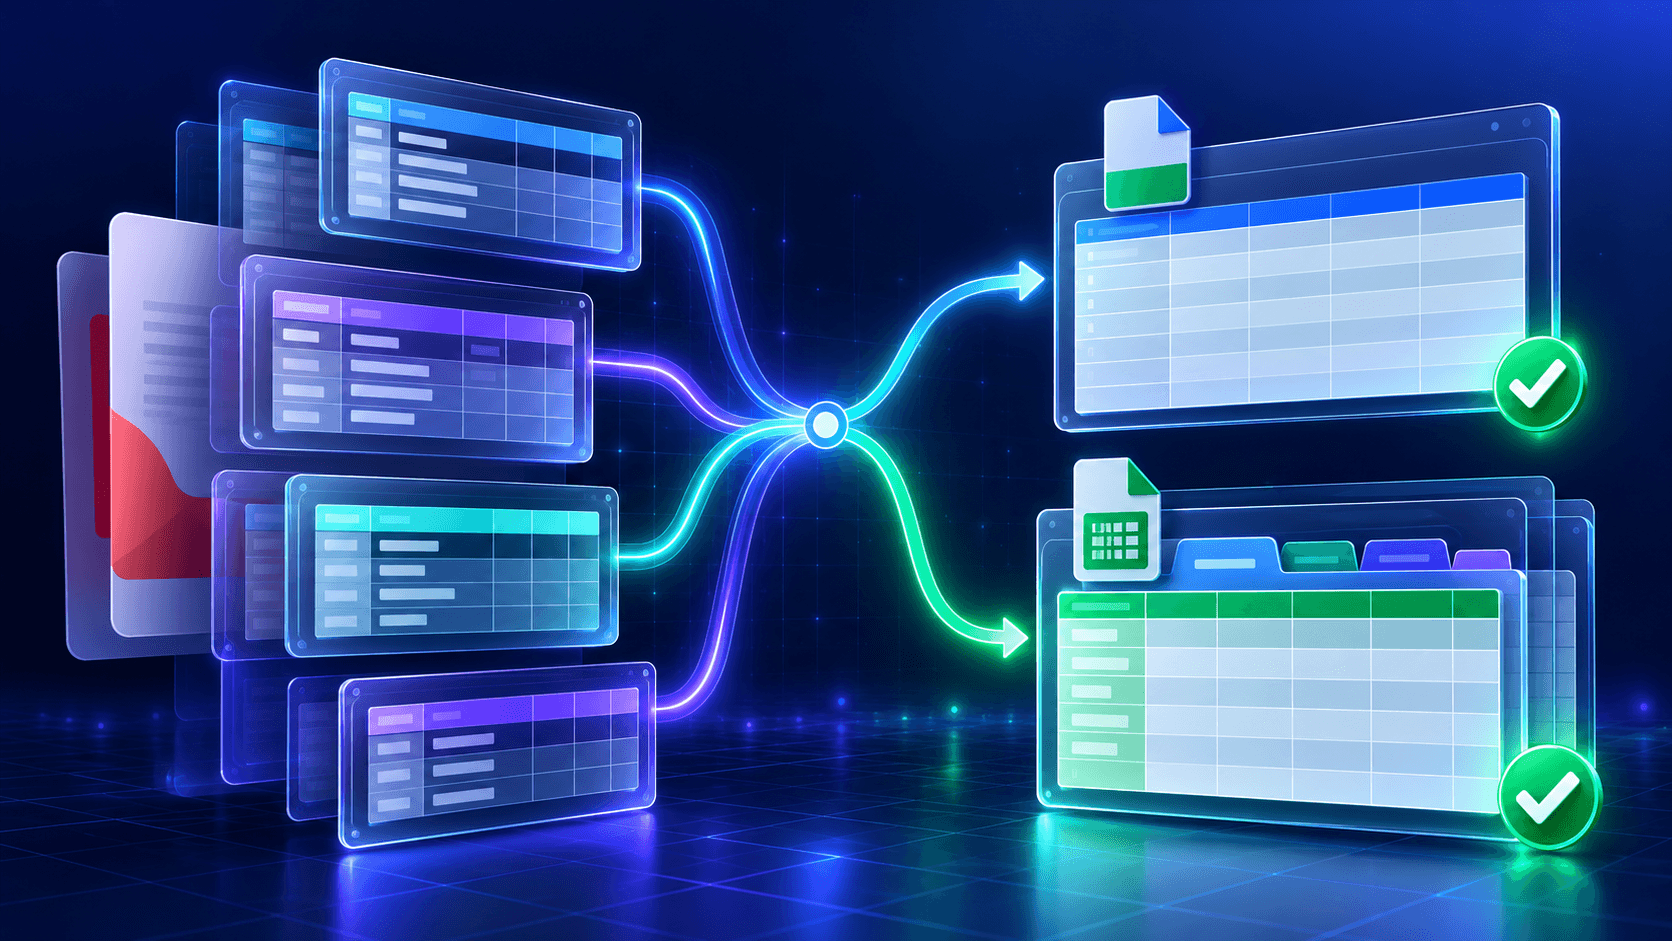
A workbook can keep each table on its own named worksheet, preserving separation and review context.
Combining tables into one worksheet is useful only when their structures are compatible.
Do not confuse format with accuracy
XLSX does not repair an incorrect extraction, and CSV does not remove ambiguity. Accuracy comes from source comparison and cleanup before export.
Verify the receiving workflow
Open the generated file in the intended application. Confirm encoding, decimal separators, leading zeros, date interpretation and worksheet names before delivery.
Put the workflow into practice
Choose a searchable PDF, tune the page scope, compare detected regions with editable grids, then export and verify only the reviewed tables.
Try Extract Tables from PDFFrequently asked questions
Clear answers before you extract tables
Which format supports multiple sheets?
XLSX supports multiple worksheets; CSV represents one flat table per file.
Can multiple CSV files be downloaded together?
Yes. Multiple selected tables are packaged into a ZIP.
Which format is better for automation?
CSV is often simpler for scripts and databases, while XLSX suits reviewed workbook delivery.
Will PDF formatting be preserved?
No. Extraction targets table values and structure rather than visual styling.