On this page
Direct extraction reads encoded characters
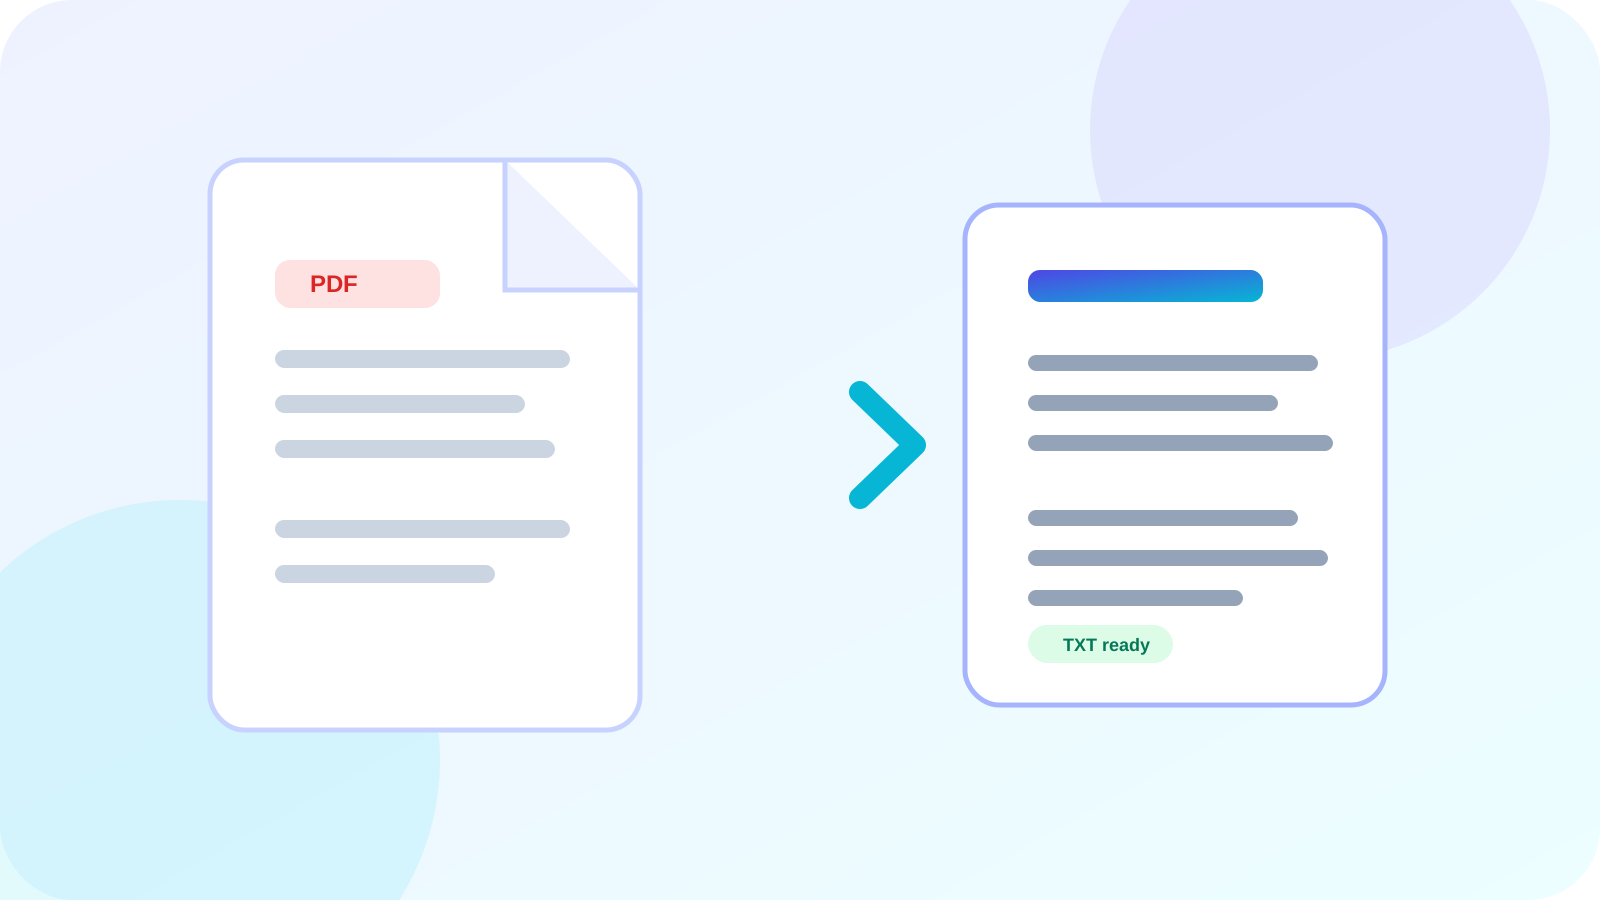
When text is embedded in the PDF, extraction can recover it without interpreting pixels. It is usually faster and avoids recognition mistakes.
Reading order still depends on how the PDF creator positioned characters, so complex layouts may need cleanup.
OCR interprets page pixels
OCR renders a page and predicts the characters visible in the image. It is essential for scanned paperwork but can confuse similar glyphs, faint marks, handwriting, or skewed lines.
Choose the smallest necessary workflow
Try direct extraction first for a digitally generated PDF. Use OCR when the result is empty or the page is clearly a scan. Mixed PDFs may need both methods page by page.
| Source | Best starting point | Review priority |
|---|---|---|
| Digital PDF | Direct extraction | Reading order |
| Scanned PDF | OCR | Recognition accuracy |
| Mixed document | Direct extraction plus OCR fallback | Page-by-page consistency |
Put the workflow into practice
Compare direct PDF text extraction with optical character recognition for scans, screenshots, and mixed documents.
Try Extract PDF TextFrequently asked questions
Clear answers before you extract
Is OCR more accurate than direct extraction?
Not for a healthy text layer. Direct extraction reads encoded characters, while OCR estimates characters from pixels.
Can one PDF contain both kinds of pages?
Yes. Mixed documents often contain digital pages, scans, or screenshots in one file.
Does OCR improve the visible scan?
No. OCR adds recognized text; it does not repair the image itself.